Abstract
Vision models for embodied intelligence require efficient 3D comprehension and interaction with objects. Existing 3D reconstruction models either overlook instance-level perception or rely on time-consuming offline reasoning, showing a less adaptability in real-time embodied scenario.
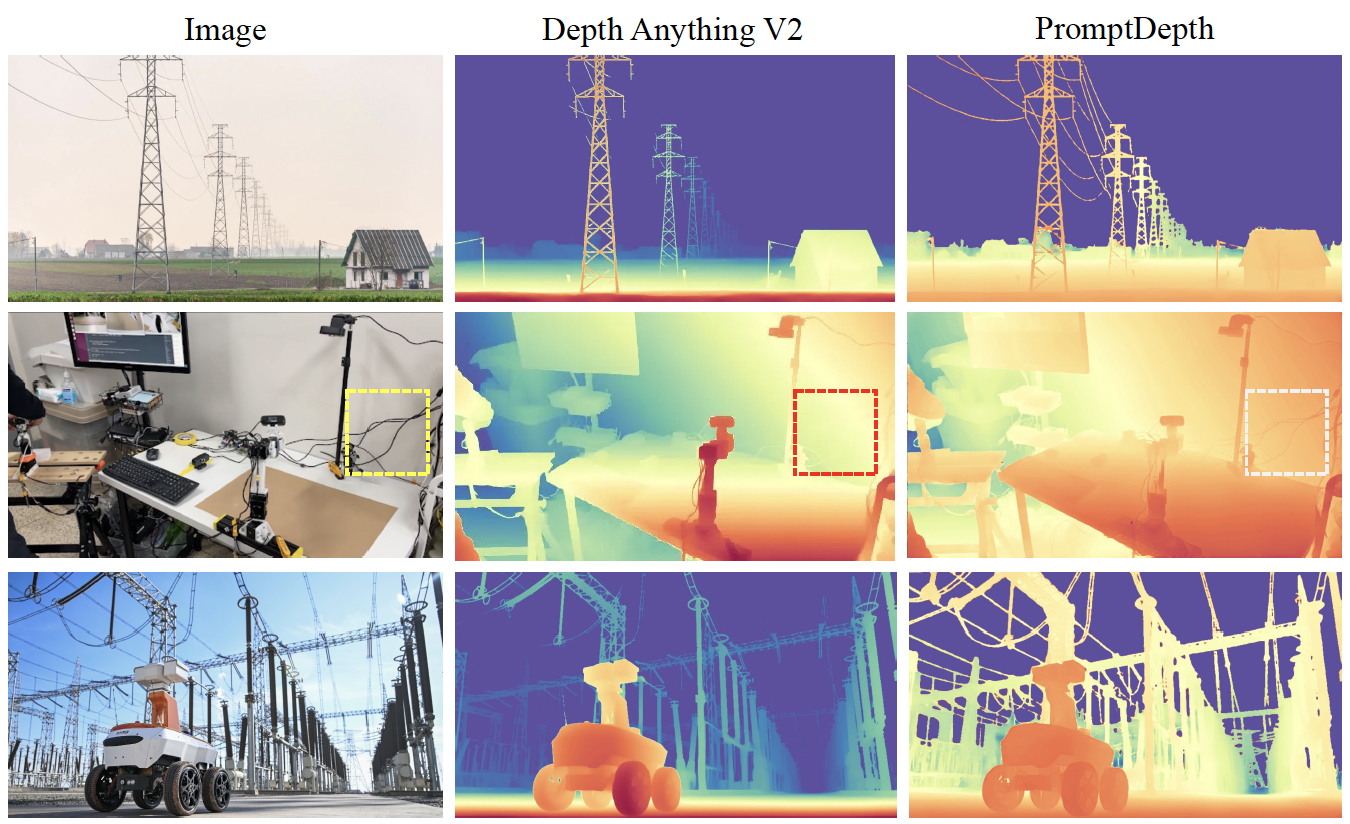
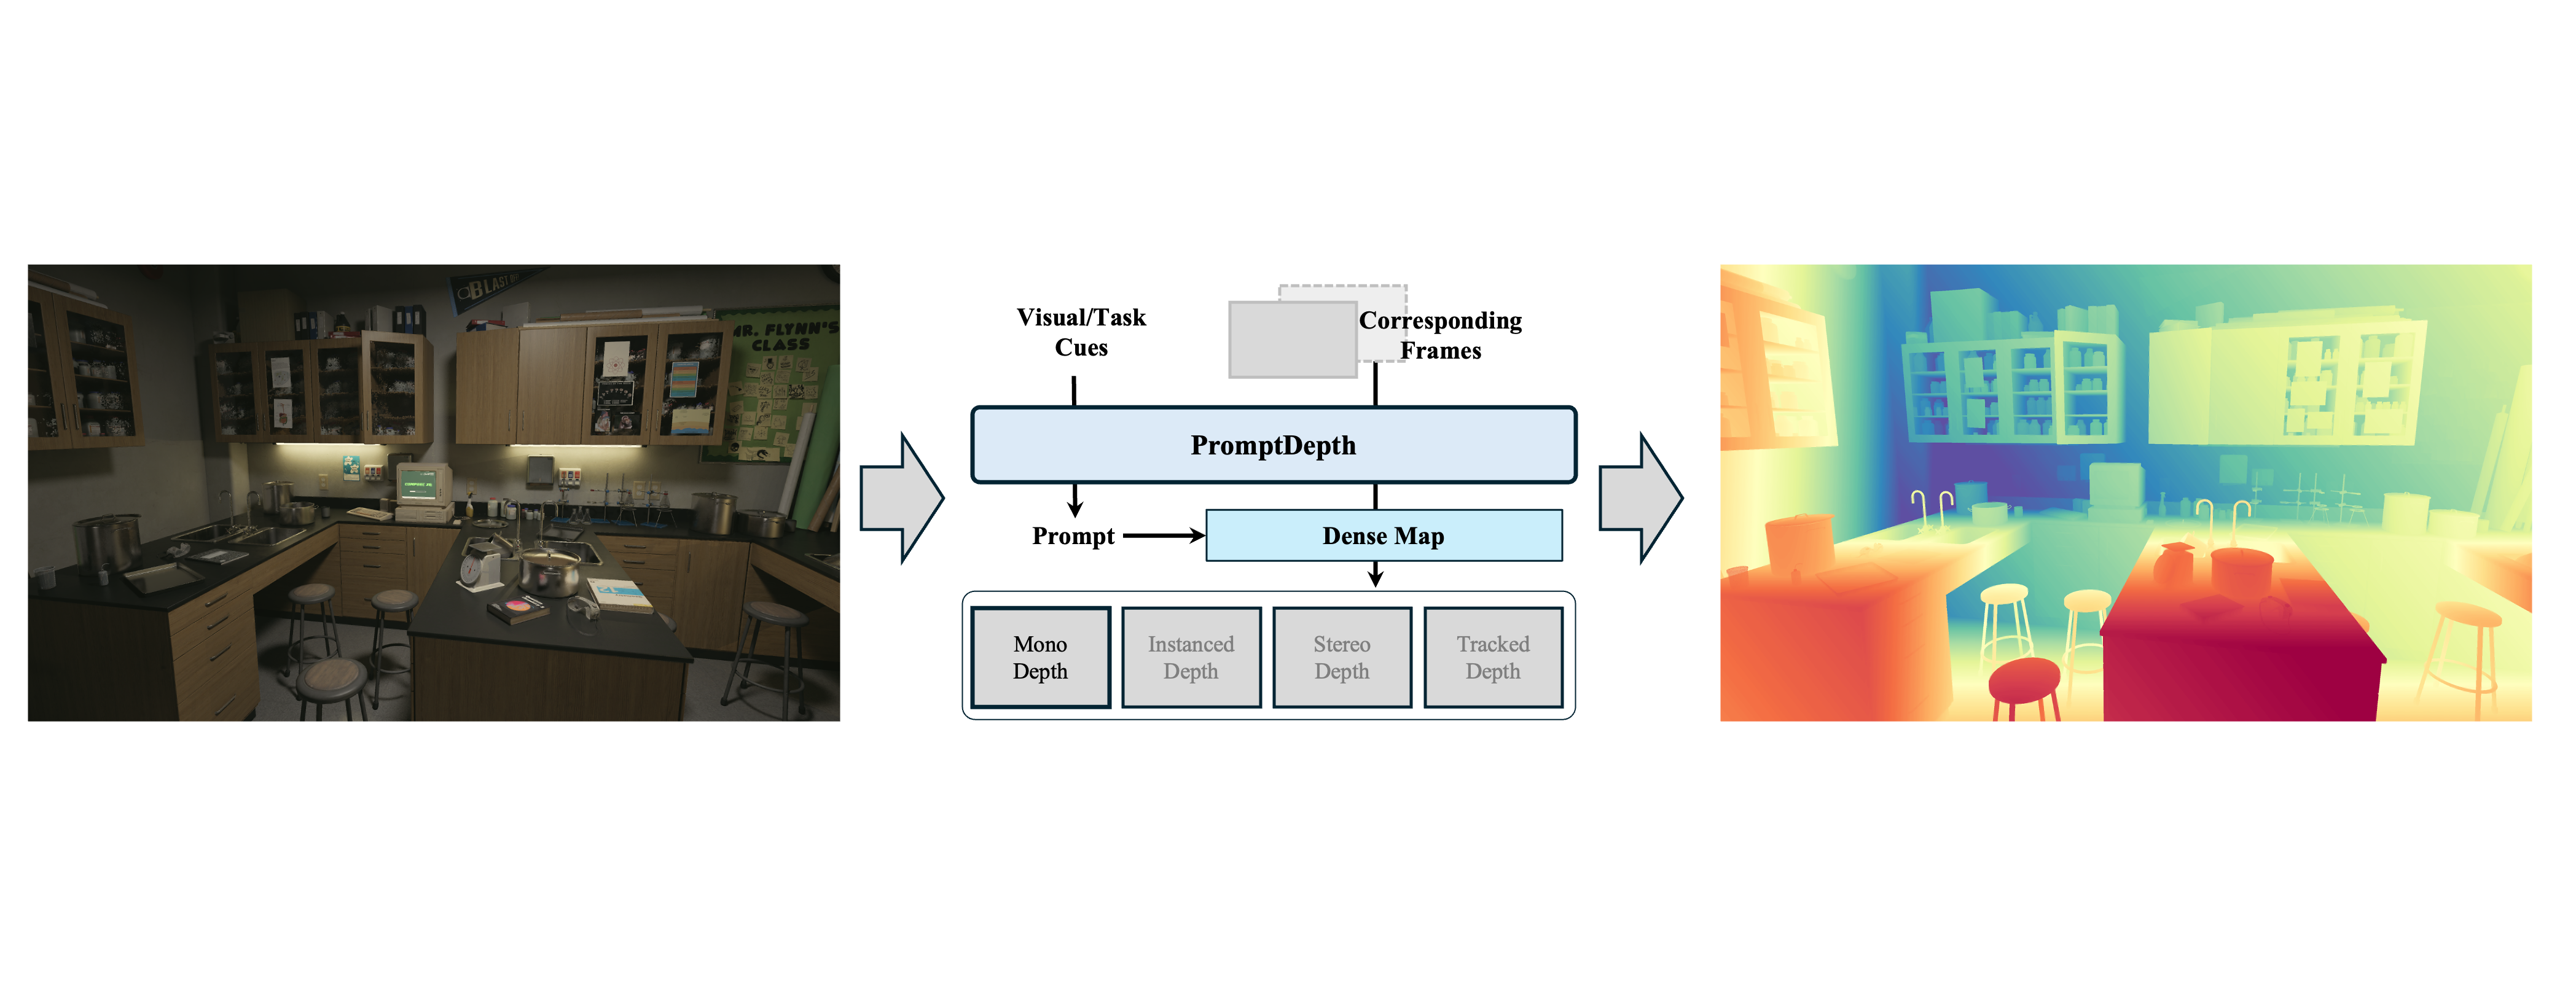
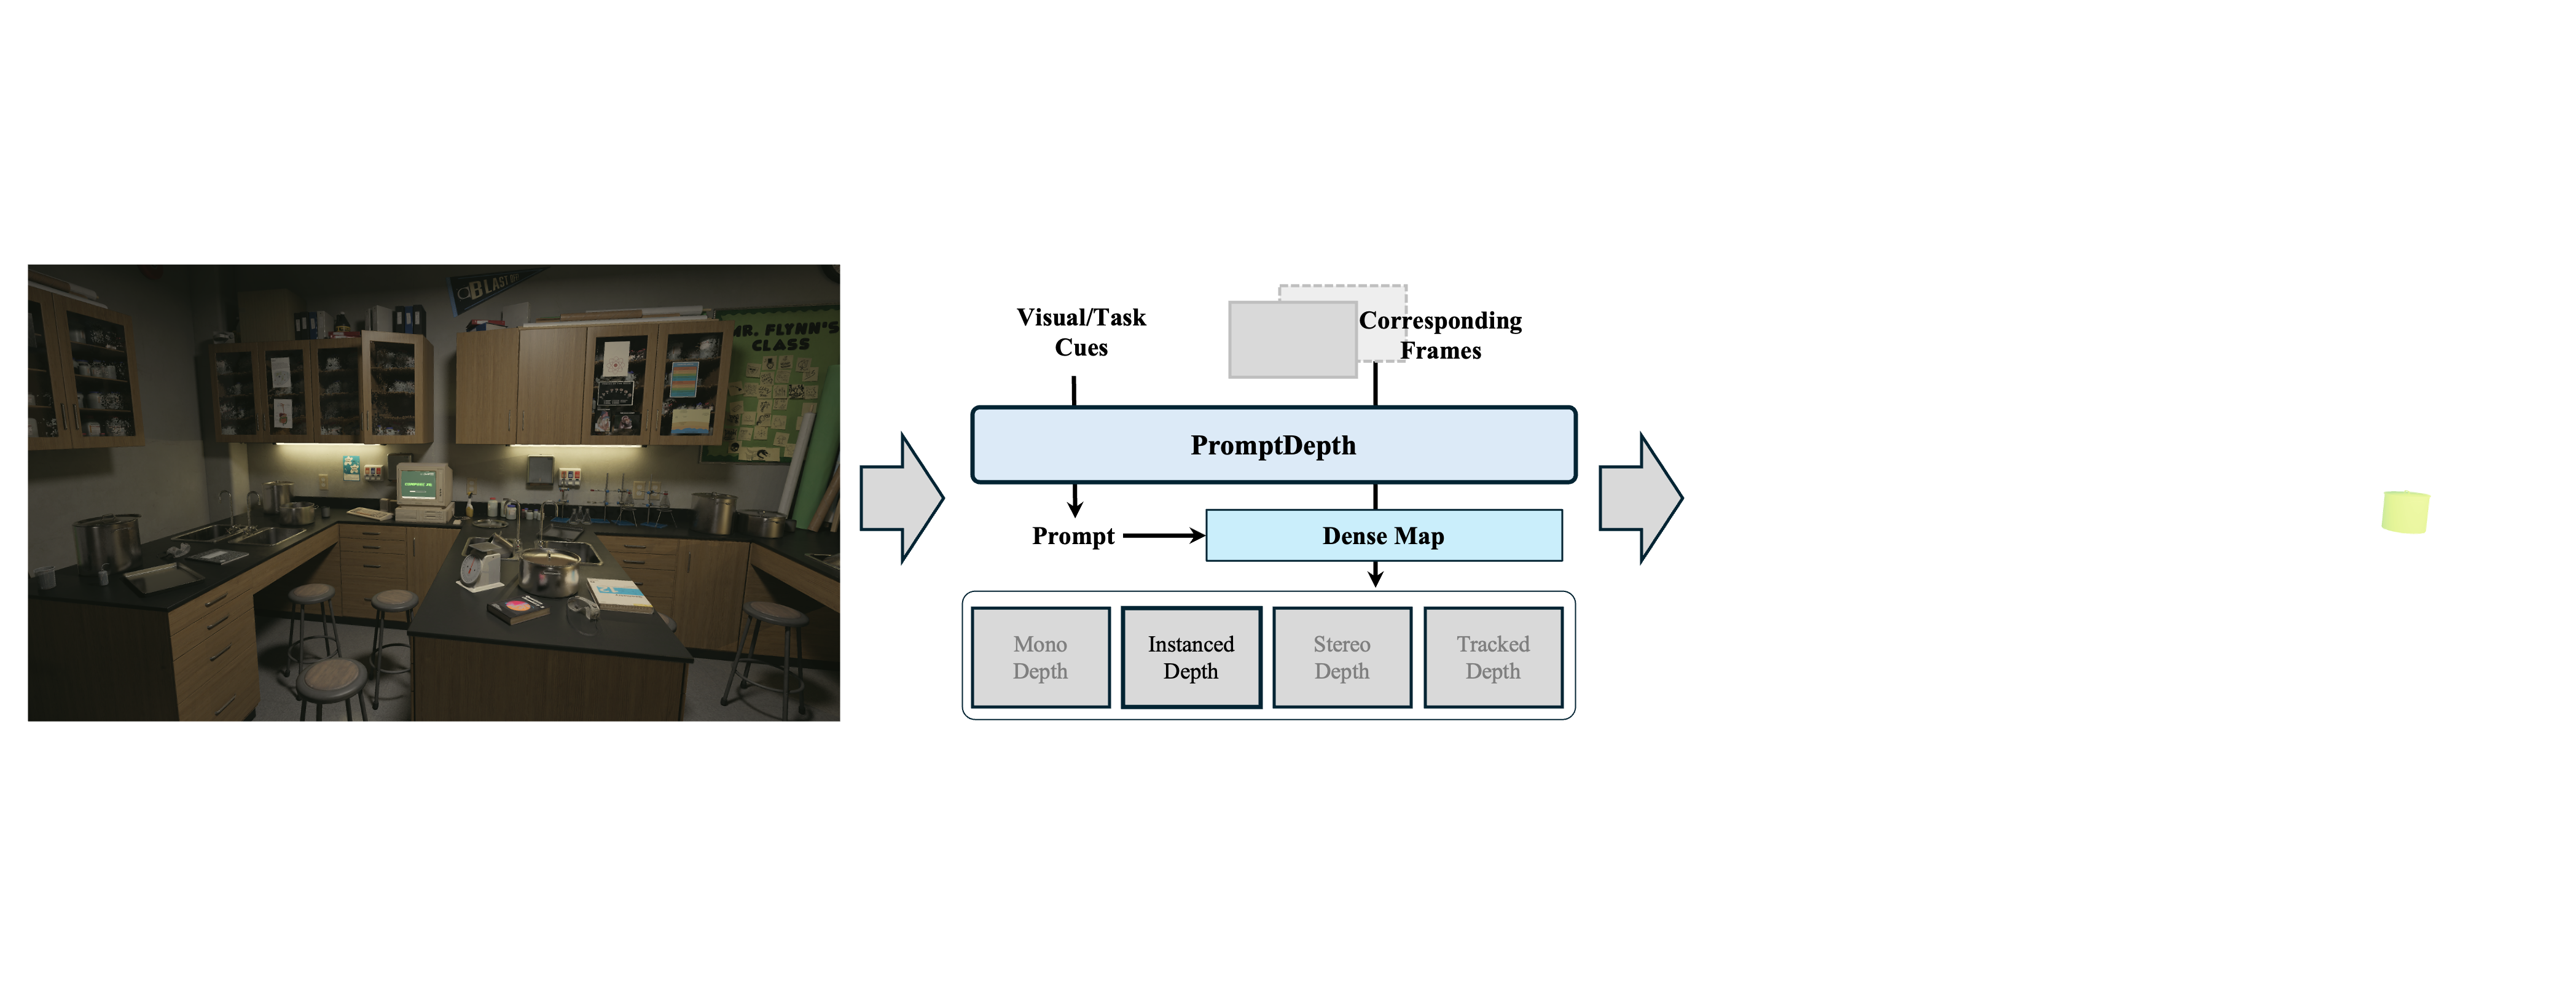
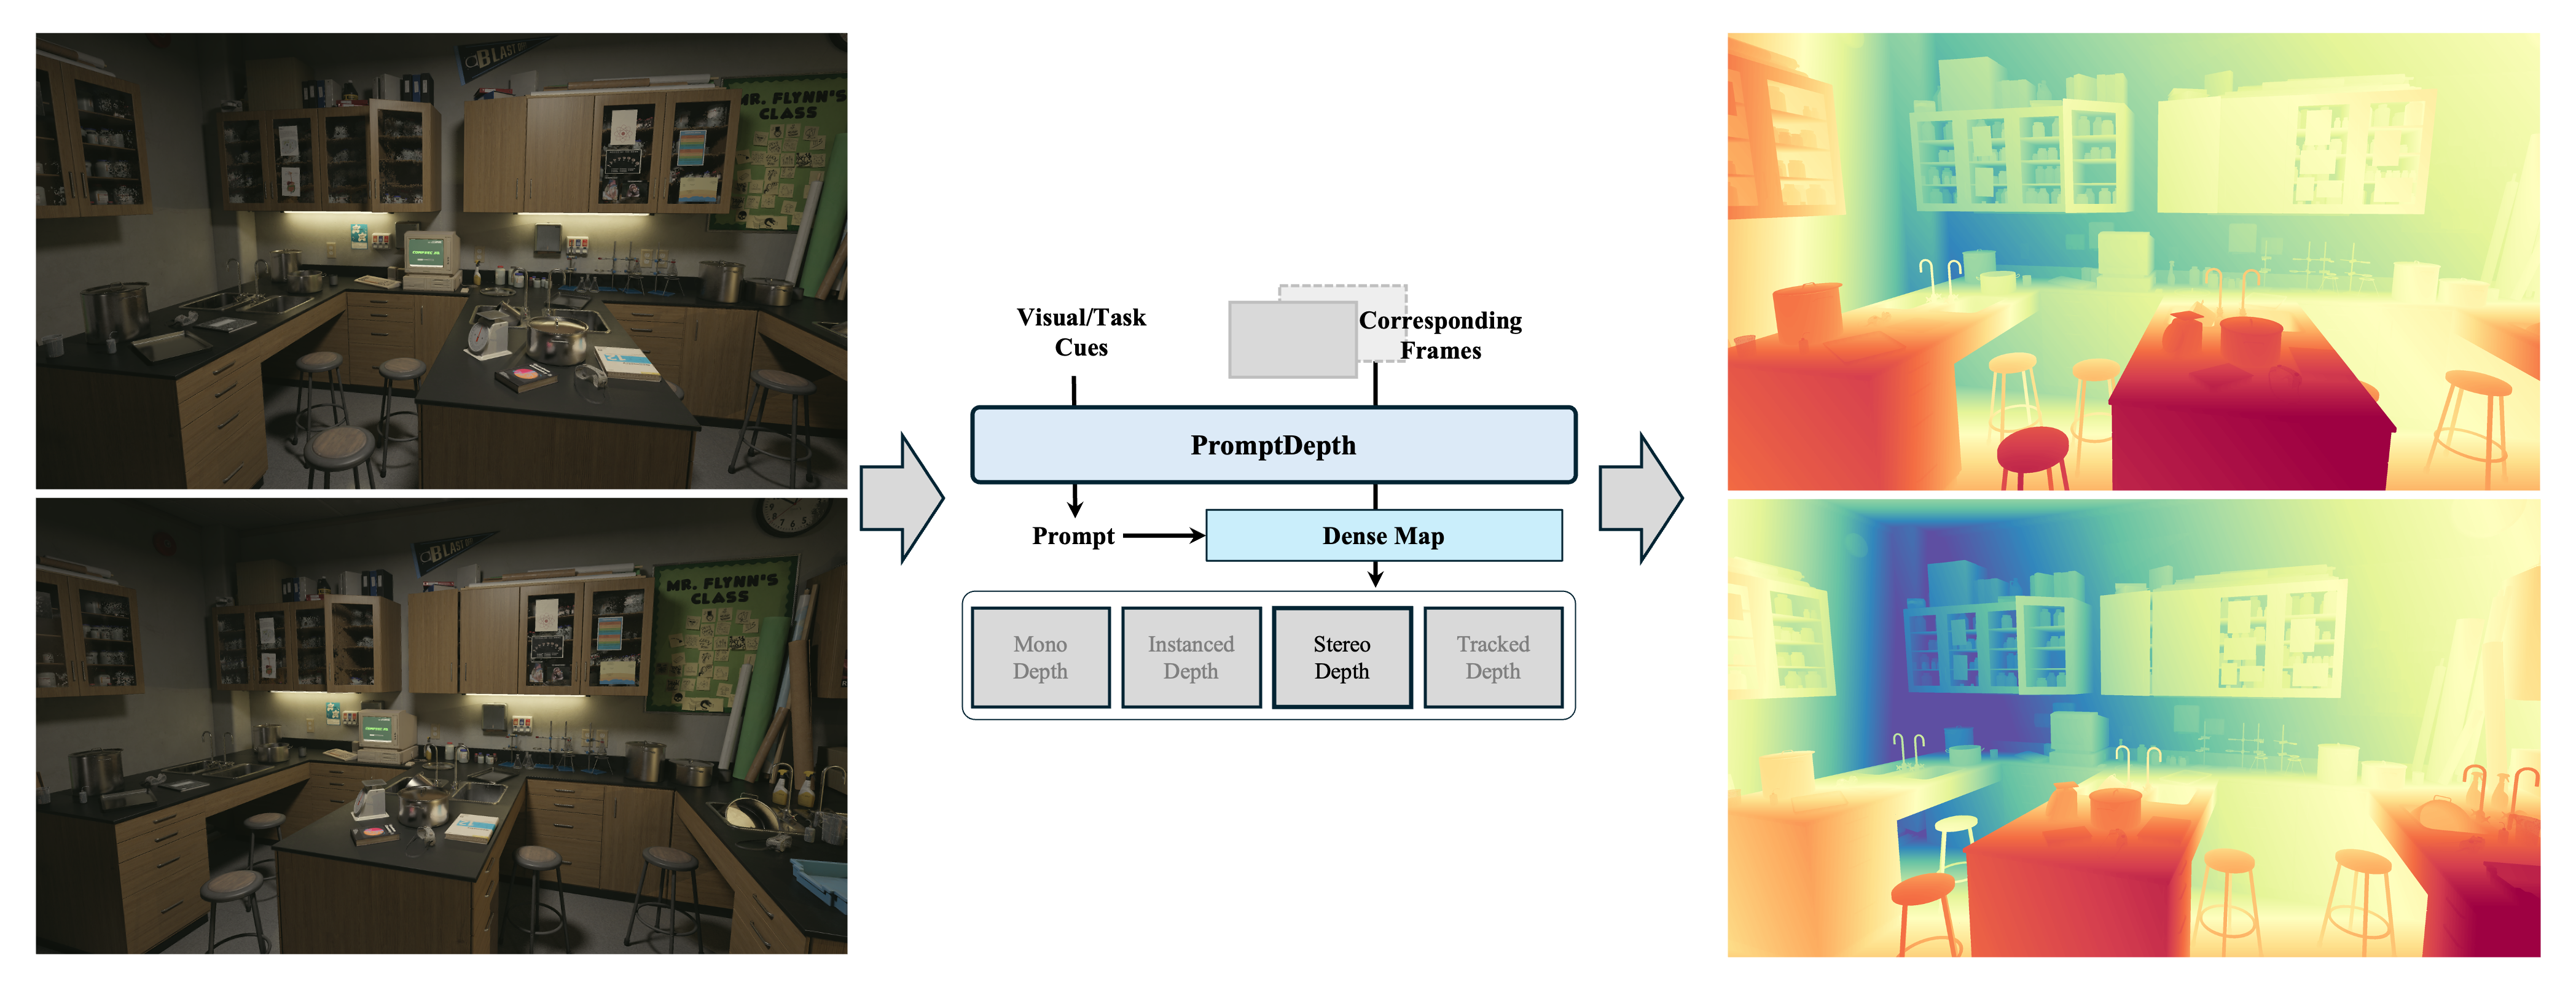
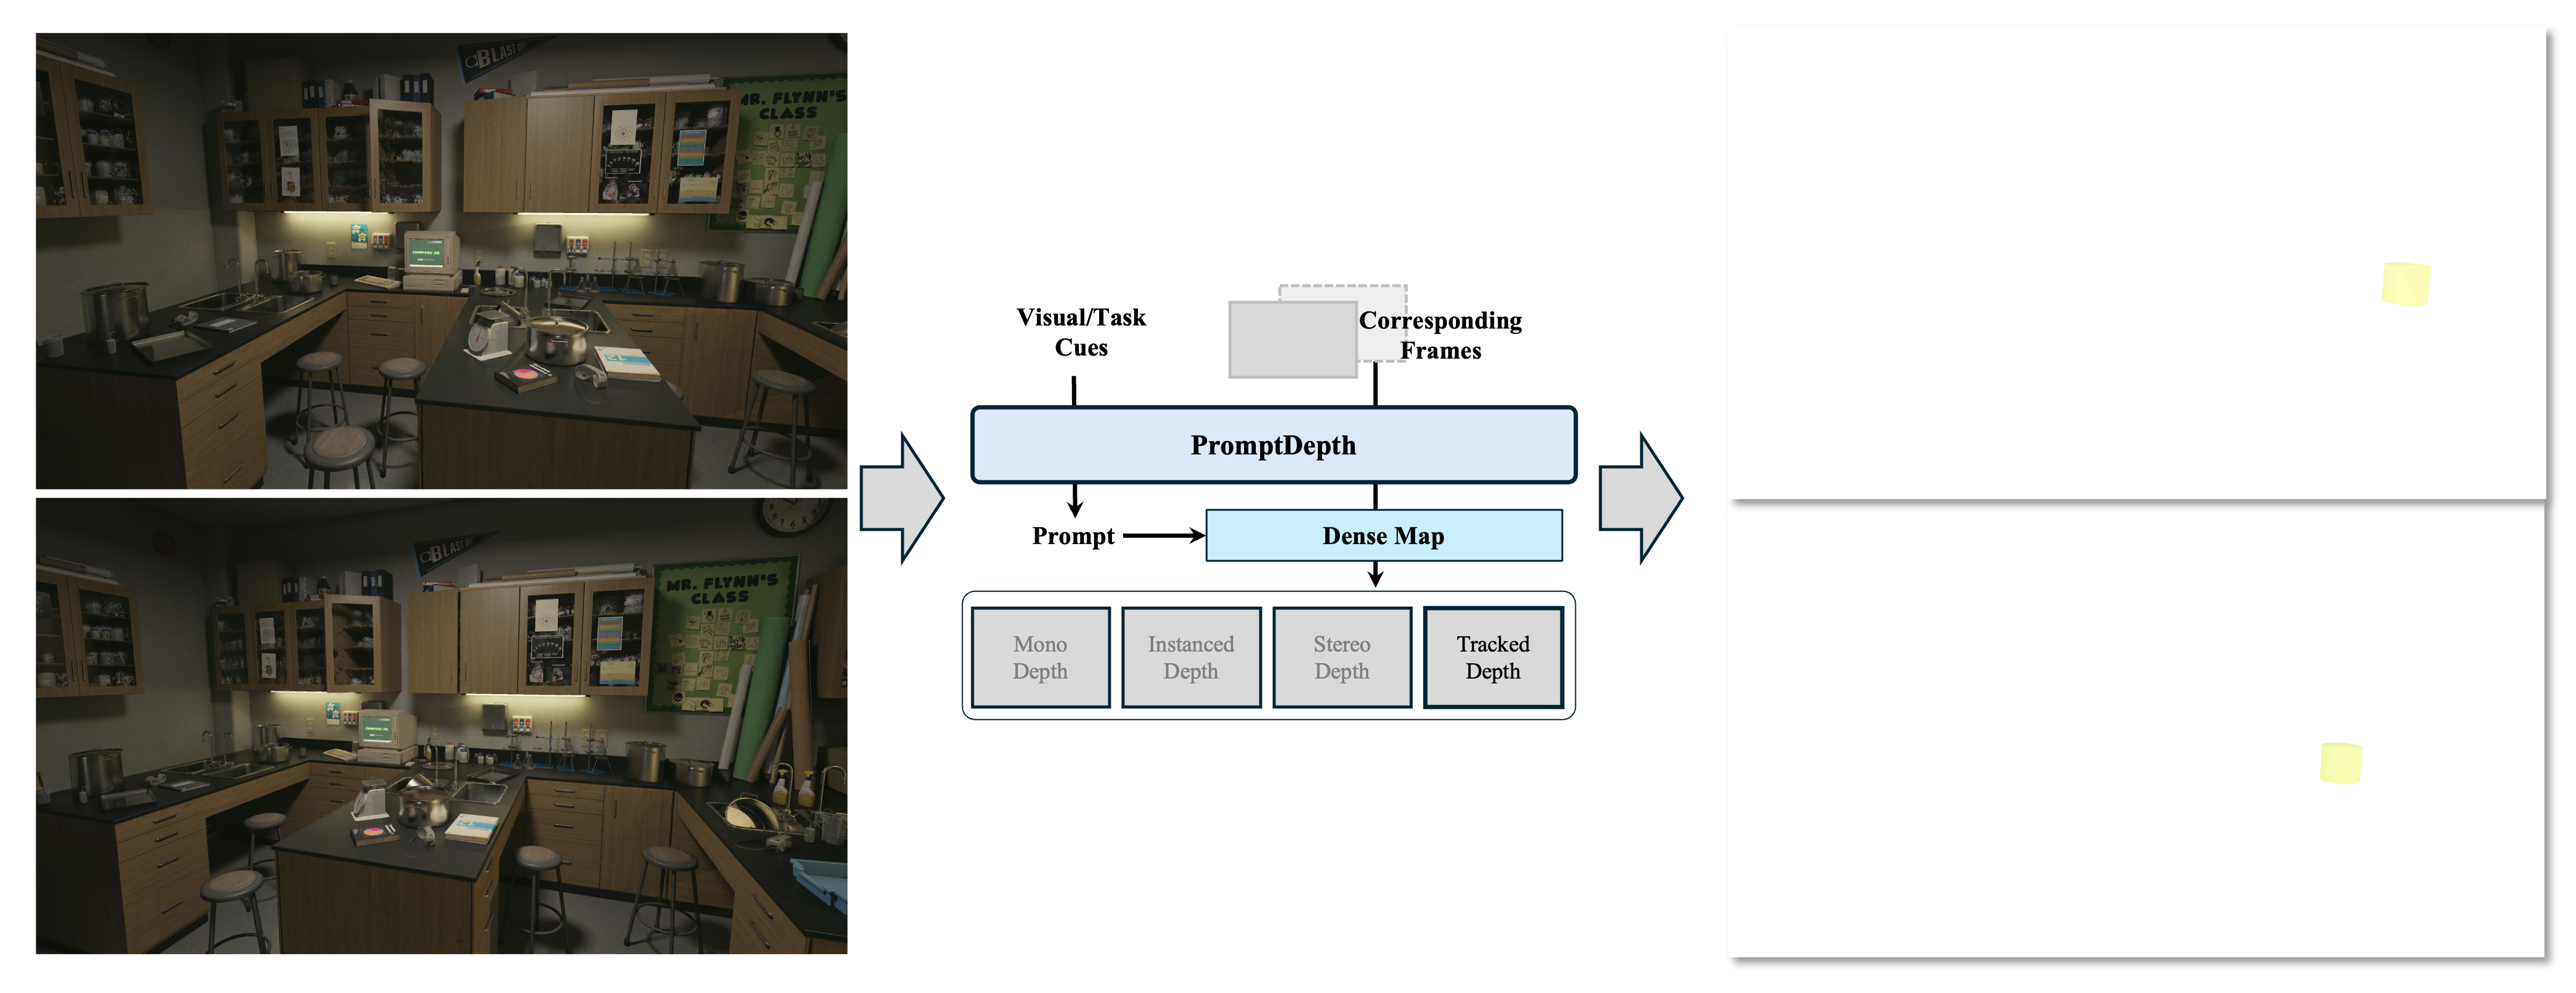
In this page, we present PromptDepth, the first promptable vision model that features both geometric 3D understanding and instance-level interaction especially designed for embodied intelligence. PromptDepth is a feed-forward network that quickly yields panoptic, instanced, or tracked depth map from two corresponding frames, enabling real-time infer sequences from embodied agents. Specifically, following the minimal prediction problem, we design a promptable Dense Prediction Transformer, making it flexible to interact with unified dense prediction according to a specific prompt. Considering the substantial discrepancy between panoptic and instanced depth map, we further introduce a novel Instanced Label Distribution Smoothing (ILDS) loss, followed by Gram Anchoring, to mitigate the inherent conflict between dense and discrete representation.
Trained on synthetic data only, our model achieves SOTA results in both depth estimation and interactive segmentation on public benchmarks. Extensive experiments demonstrate superior visual efficiency in embodied tasks compared to current fundamental models. We believe that our efficient and flexible geometric 3D model offers a new foundation for vision tasks in embodied intelligence.
Promptable Geometric Perception
PromptDepth leverages flexible interaction and task encoding to perform lightweight geometric estimation while segmenting regions of interest. It provides a novel minimal-prediction formulation for multi-task learning.
Dataset
High-fidelity
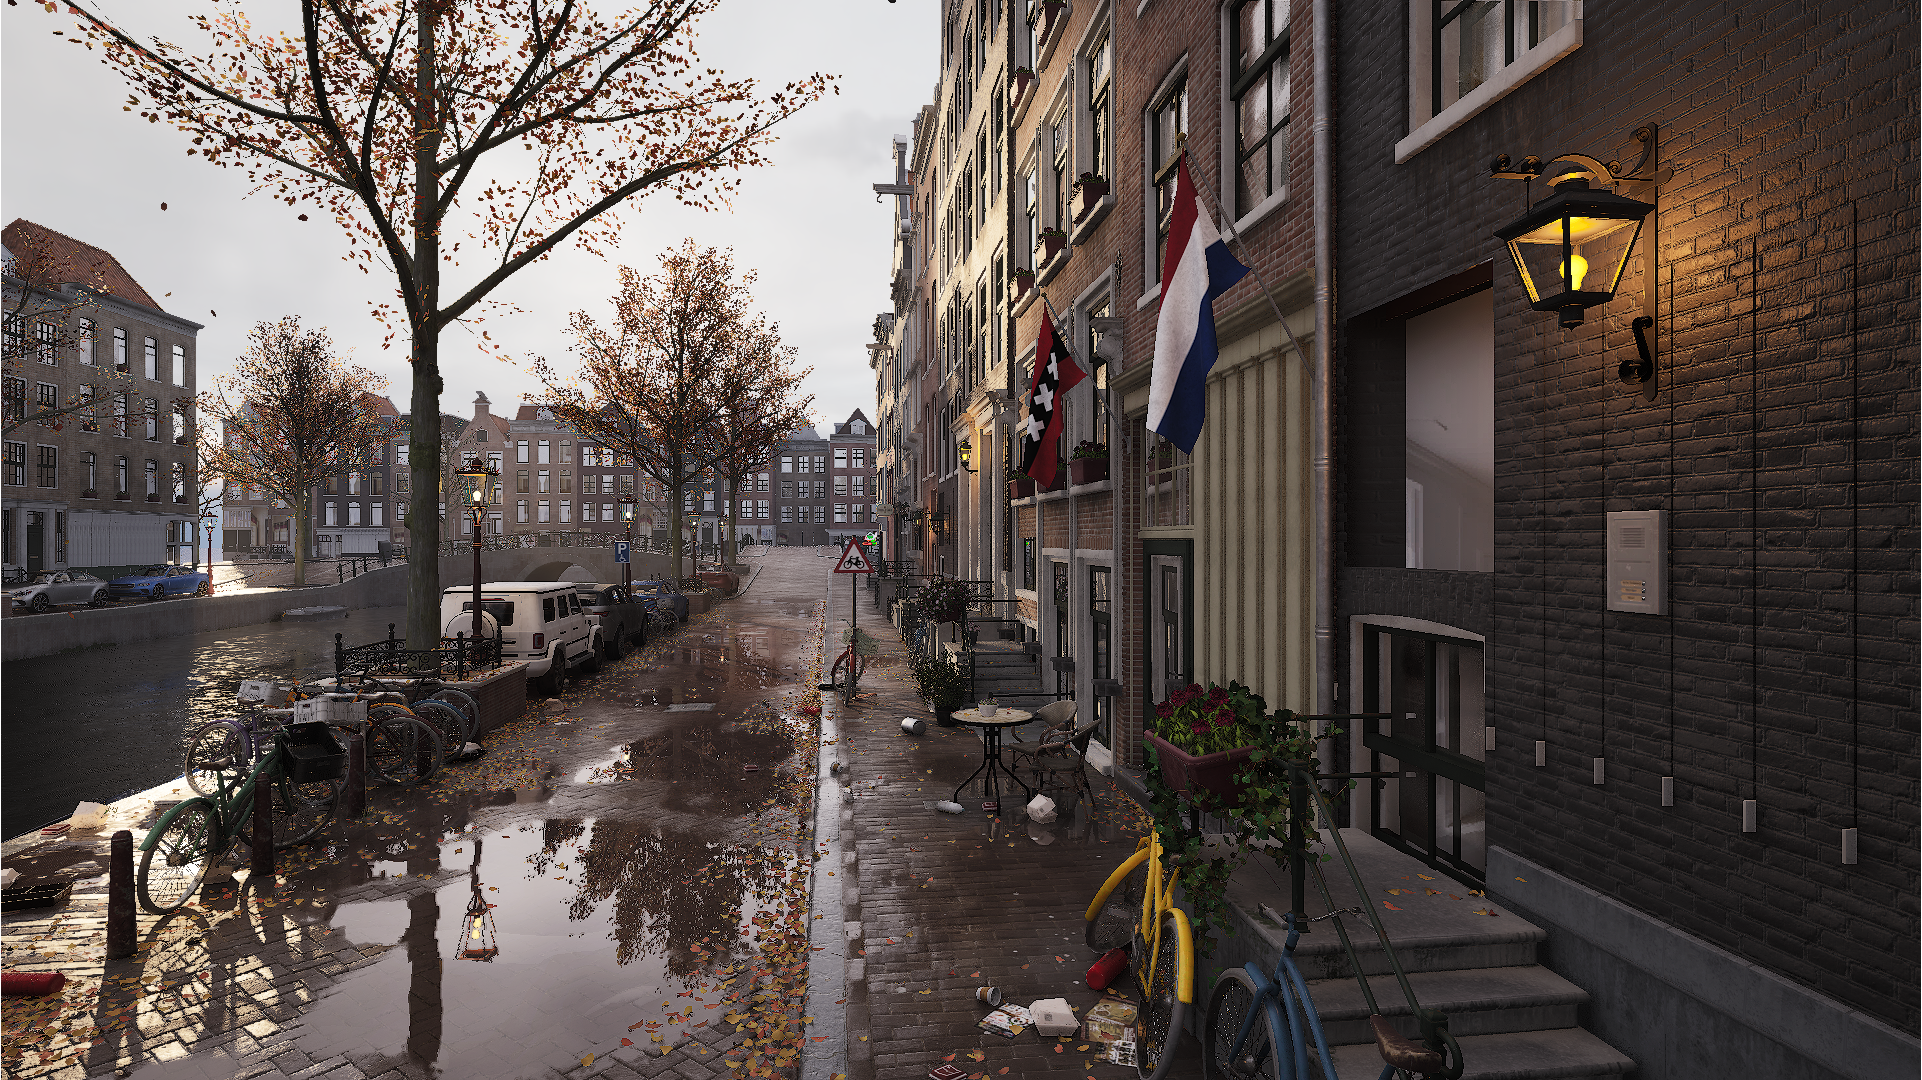
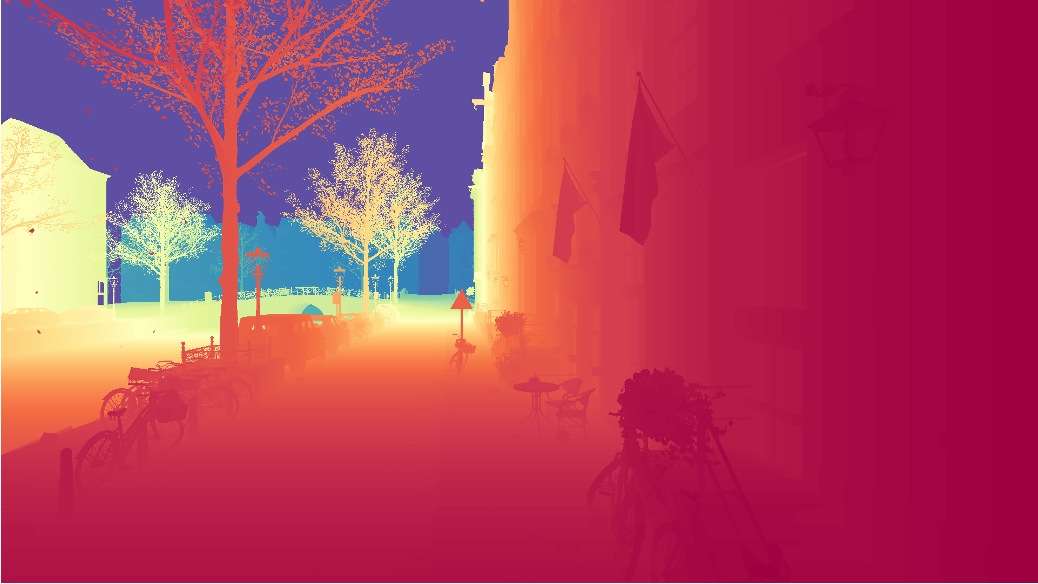
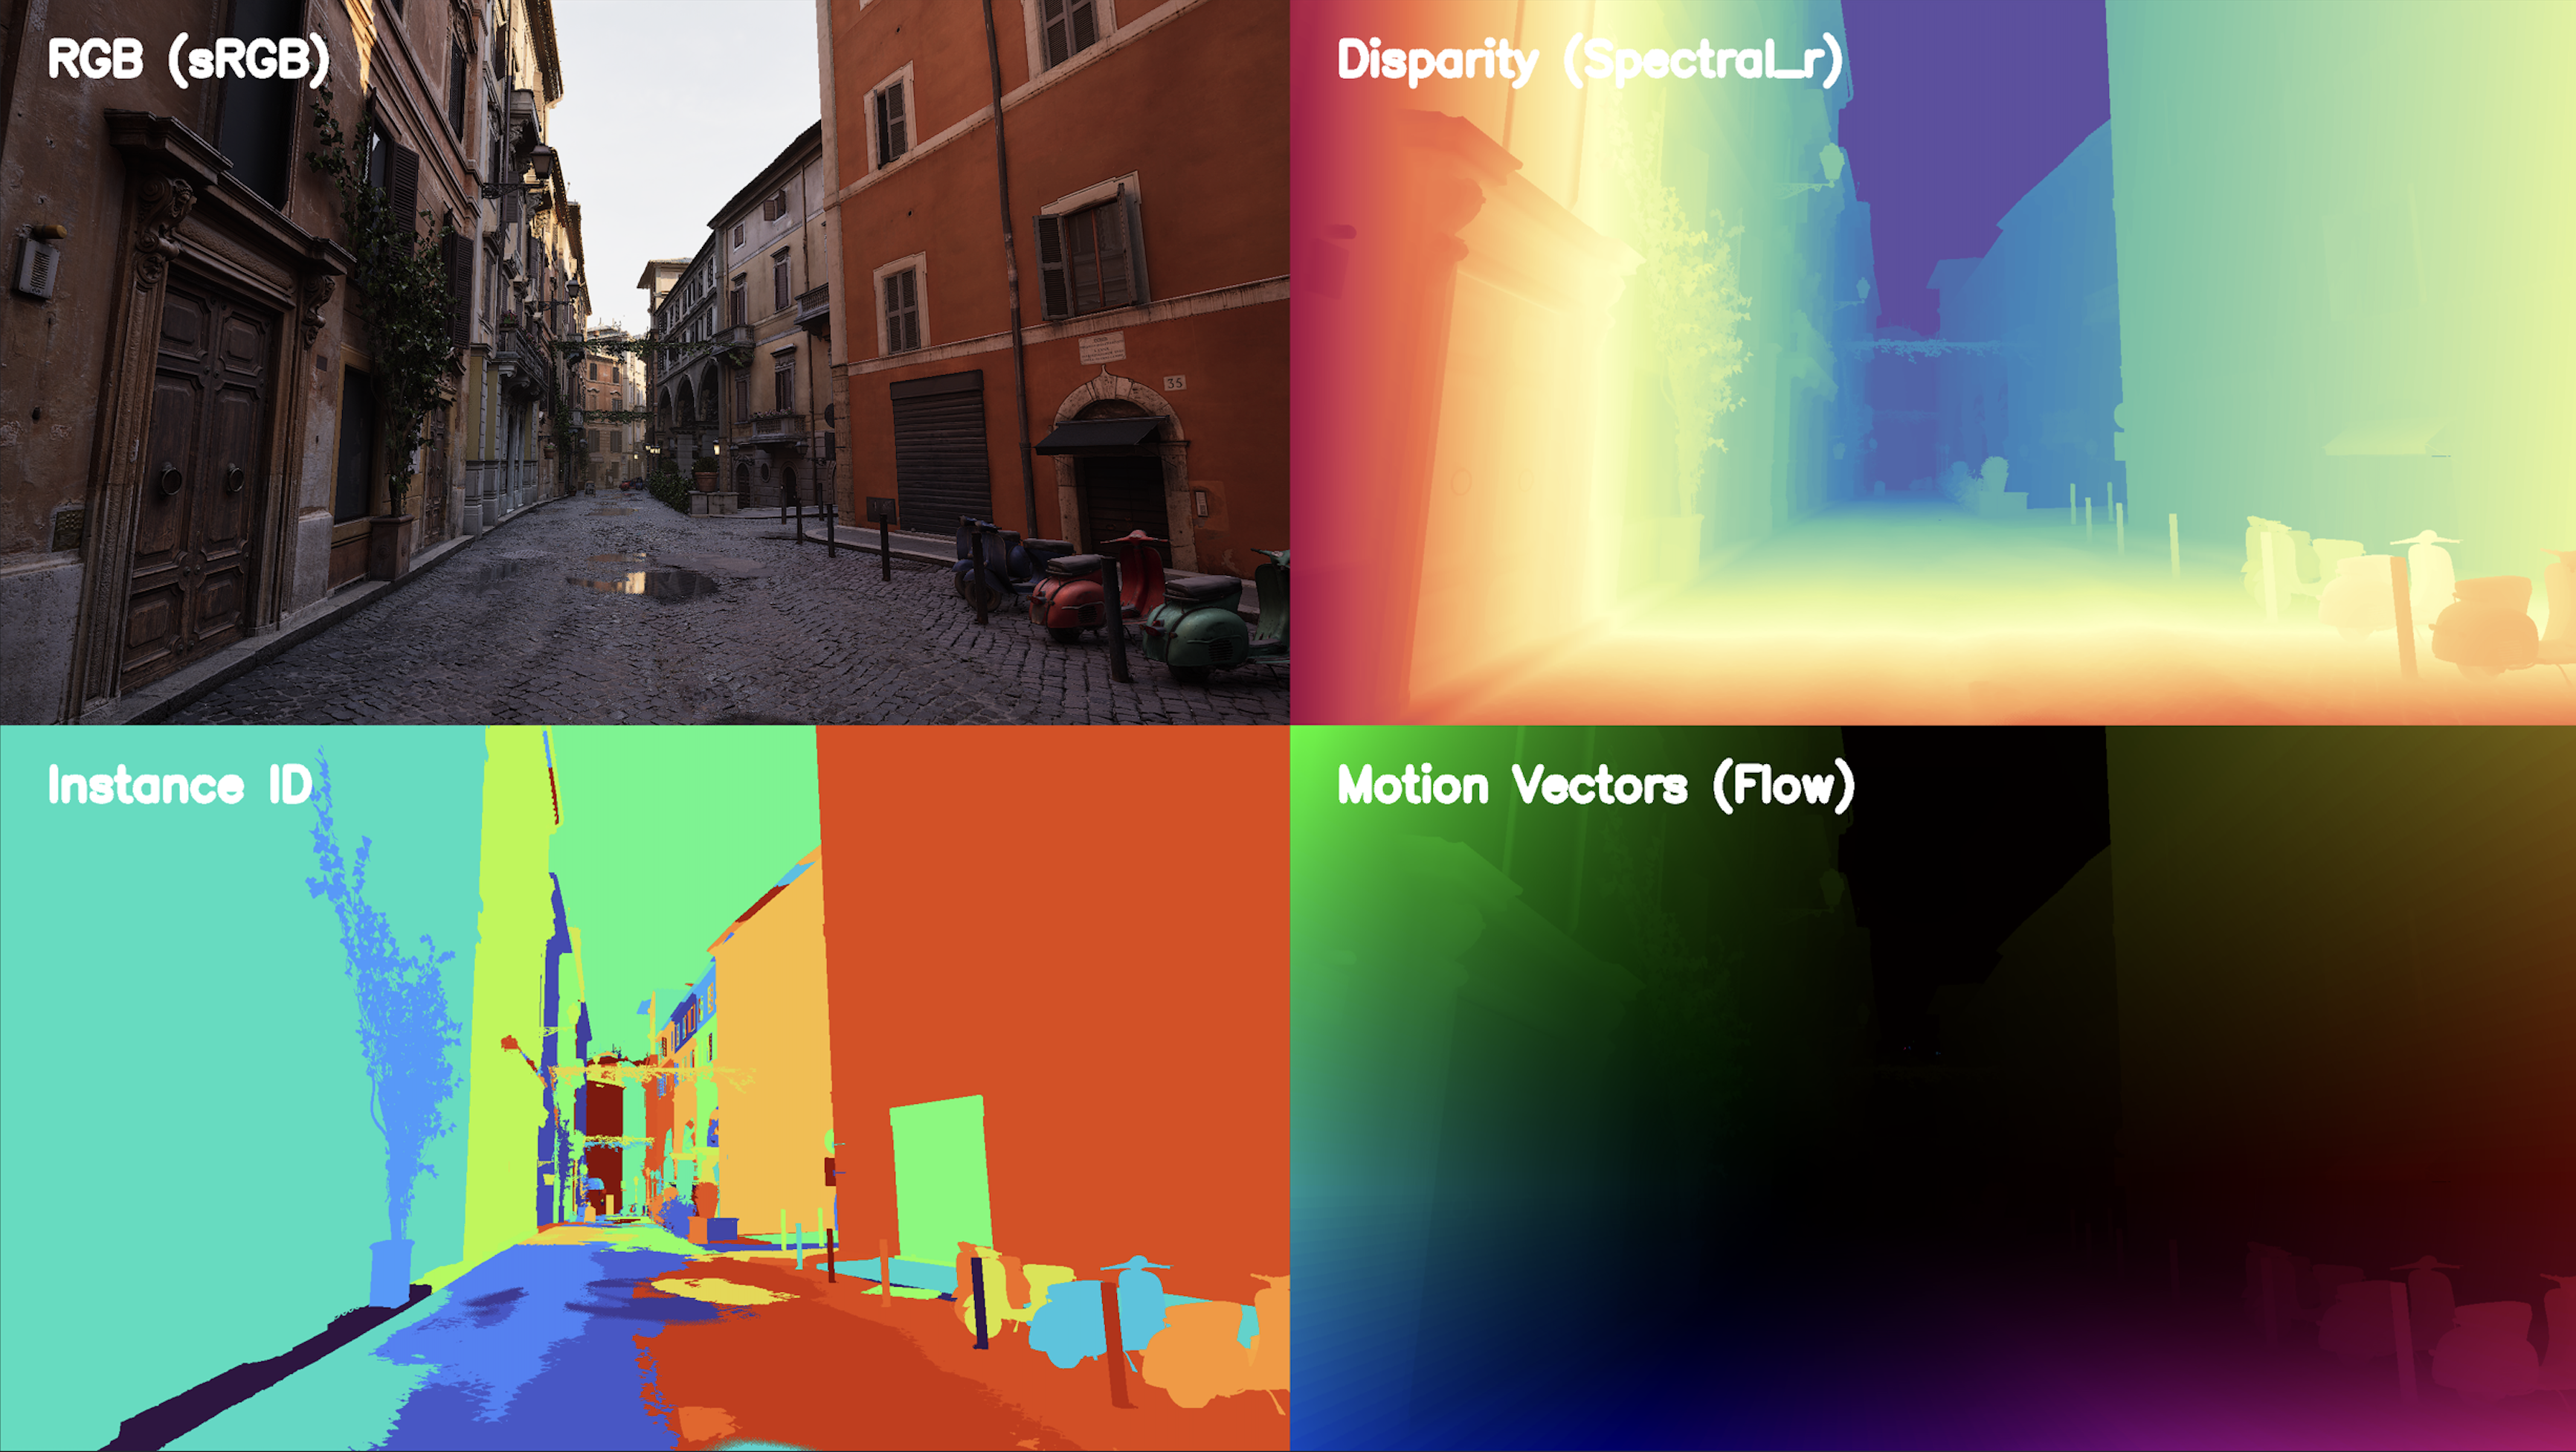
Using Movie Render Queue, an offline rendering technique, we gather millions of images with corresponding poses, depth, optical flow, and instance mask maps. Our synthetic RGB images preserve photorealistic textures, lighting, and scene details, providing high-fidelity visual supervision for promptable geometric perception.
Large-scale
The rendered videos cover diverse environments, viewpoints, object layouts, and motion patterns, enabling broad and scalable data generation.
Well-aligned
RGB images, depth maps, semantic annotations, and optical flow are densely synchronized, ensuring highly aligned multi-modal supervision for 3D vision tasks.
Embodied Experiment
The desktop interactive demo shows controllable interactive segmentation and depth estimation. PromptDepth keeps instance depth and panoptic depth in a consistent metric scale, enabling reliable object-level reasoning within a unified scene geometry.
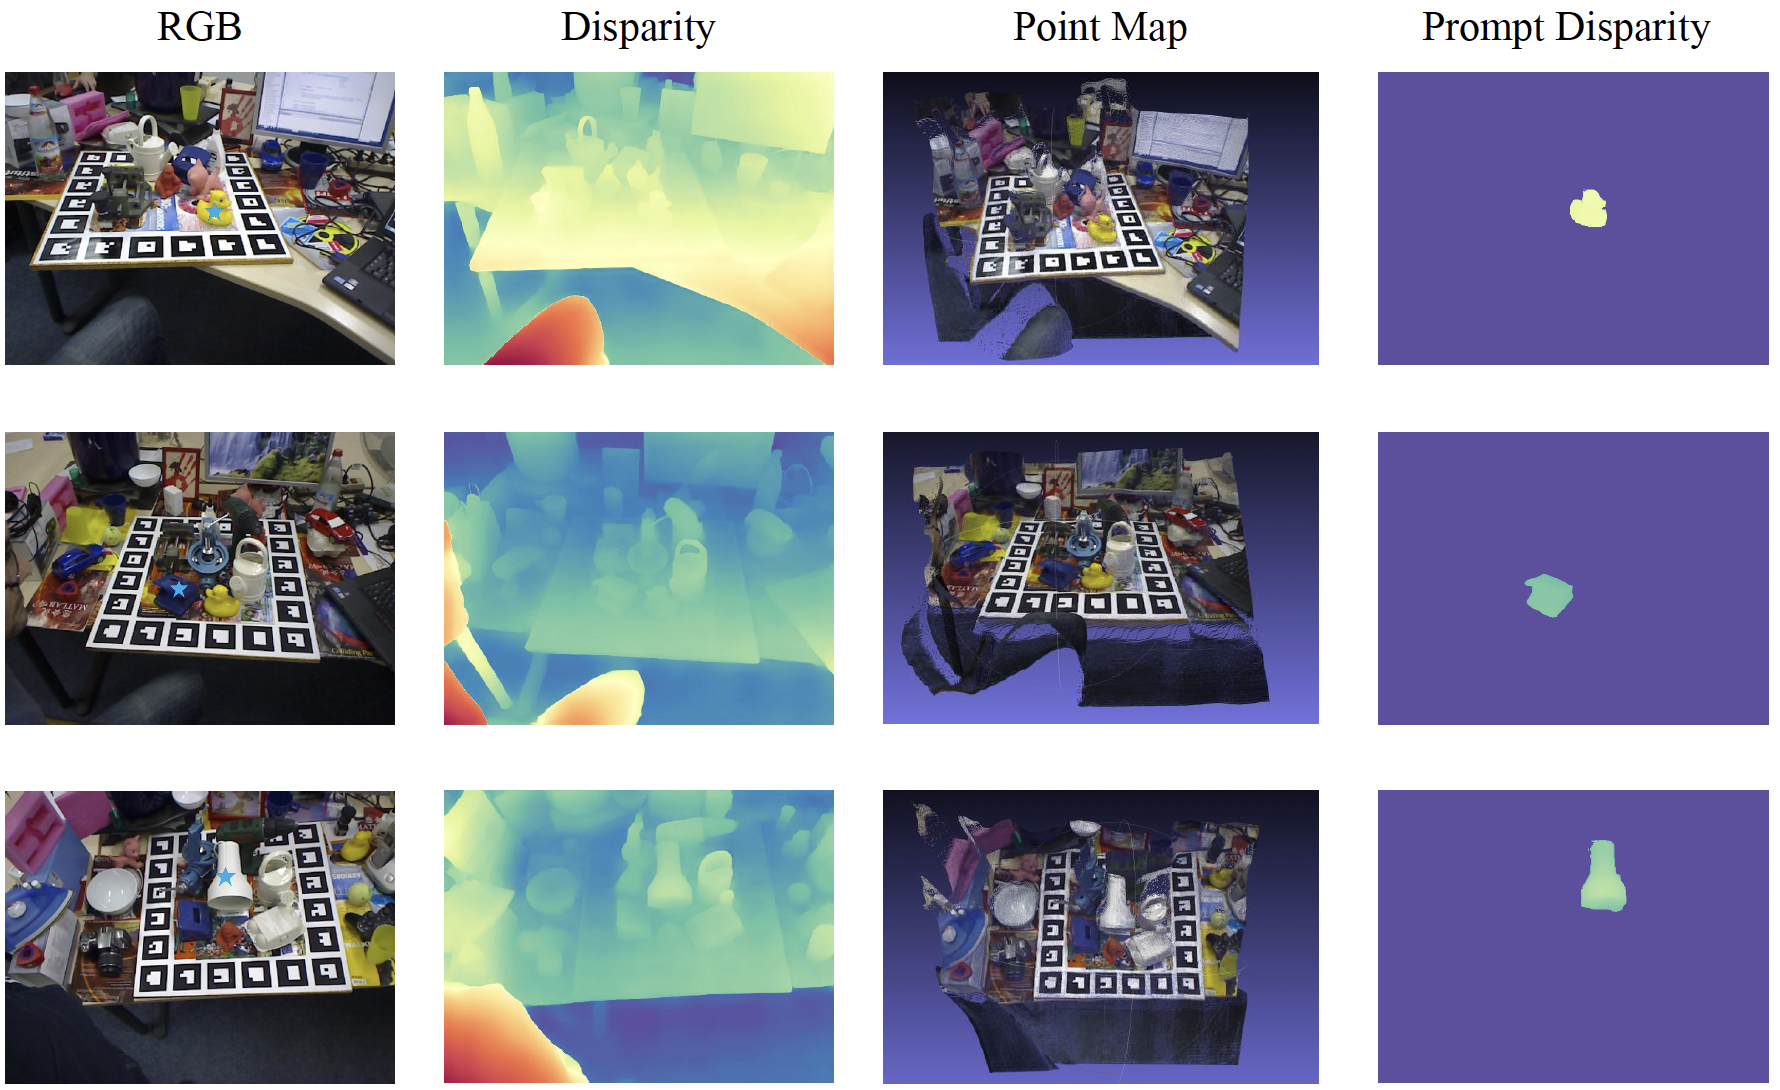
Without any fine-tuning, our model can directly achieve real-time inference in high-speed embodied scenarios, supporting downstream applications.